Distributed computing
16 articles
 Model routing
Settling one job across many operators
A single agent task can touch several independent operators: a primary that stalls, a hedge that answers, a successor that takes over a session, expert shards held on different machines. How Tenzro routes that work, settles each operator for its own part, and what the buyer, each operator and an auditor can see.
6 min read Consensus
Inside Tenzro's Consensus: DAG-Based BFT for a Network of Machines
How Tenzro orders transactions with a DAG protocol, makes finality portable with hardware-signed checkpoint certificates, hands over between committees at epoch boundaries, and checks the code against a formal model step by step.
6 min read Model routing
Build, rent or network? Sourcing AI inference in 2026
CTOs now have three ways to source AI inference: build on their own hardware, rent from a cloud or model API, or buy from an open network of independent providers. This guide compares them on the criteria that decide the outcome: demand shape, model choice, jurisdiction, verification and exit.
5 min read Consensus
Breaking Our Own Network: Chaos Testing a BFT Consensus
How we partition, restart and skew a private Tenzro network on purpose, what we check while it happens, and the class of catch-up bug that taught us to measure progress by what a node actually executed.
6 min read Simulation
 and Digital Twins at Scale, Across Many Machines
Digital twins and robot-learning pipelines run thousands of simulations. Most of that work splits cleanly across many machines. How to decompose it, where it should run, and how to trust results computed on hardware you do not own.
4 min read Distributed training
Distributed Training Across Clusters: What Works Over the WAN Today
Low-communication training has moved from paper to practice, with models trained across continents and among peers who come and go. What the research shows, what still binds, and where an open network of verifiable machines helps.
4 min read Energy and placement
Energy, power and placement: routing AI work to capacity
Power and grid connections, not chips, now limit where AI capacity can grow. This article sets out what the IEA, the US Department of Energy and EU rules say about data-centre electricity, and why routing flexible inference to where power and capacity already exist is a policy and engineering lever.
5 min read Distributed computing
From idle capacity to served inference: what operators need
Inference demand rises and falls through the day, so most AI capacity has spare hours. This article covers the five things a data-centre operator needs to sell those hours on an open network: machine identity, a trusted model supply, metering, proof of availability and direct settlement.
5 min read Distributed computing
GPU operators: sell compute on verifiable service levels
Conventional cloud SLAs are measured by the provider, and the customer has to claim any credit. On an open market of independent GPU operators, availability and output have to be verified by someone else, and payment has to follow the verification. This article explains how that works and what it changes for operators.
6 min read Inference optimization
Inference Optimisation From Consumer GPUs to the Data Centre
Quantisation, speculative decoding, continuous batching, paged and reused KV cache, and prefill/decode disaggregation: what the 2025-2026 work shows, and what each technique means when the GPUs belong to many operators on a wide-area network.
6 min read Networking
Multi-region AI: latency, jurisdiction and failover
Running AI across the EU, US and APAC forces trade-offs between distance, law and resilience. This article uses measured inter-region latencies to show what each region pair costs, how jurisdiction rules constrain failover, and how to design inference that stays fast, lawful and available when a provider fails.
5 min read Networking
 for Distributed Inference: Gossip, Re-announcement and Load
A network of machines behind home routers, carrier NAT and corporate proxies still has to deliver every transaction and every heartbeat. How Tenzro's transport, gossip budgets and re-announcement keep messages from getting lost under load.
5 min read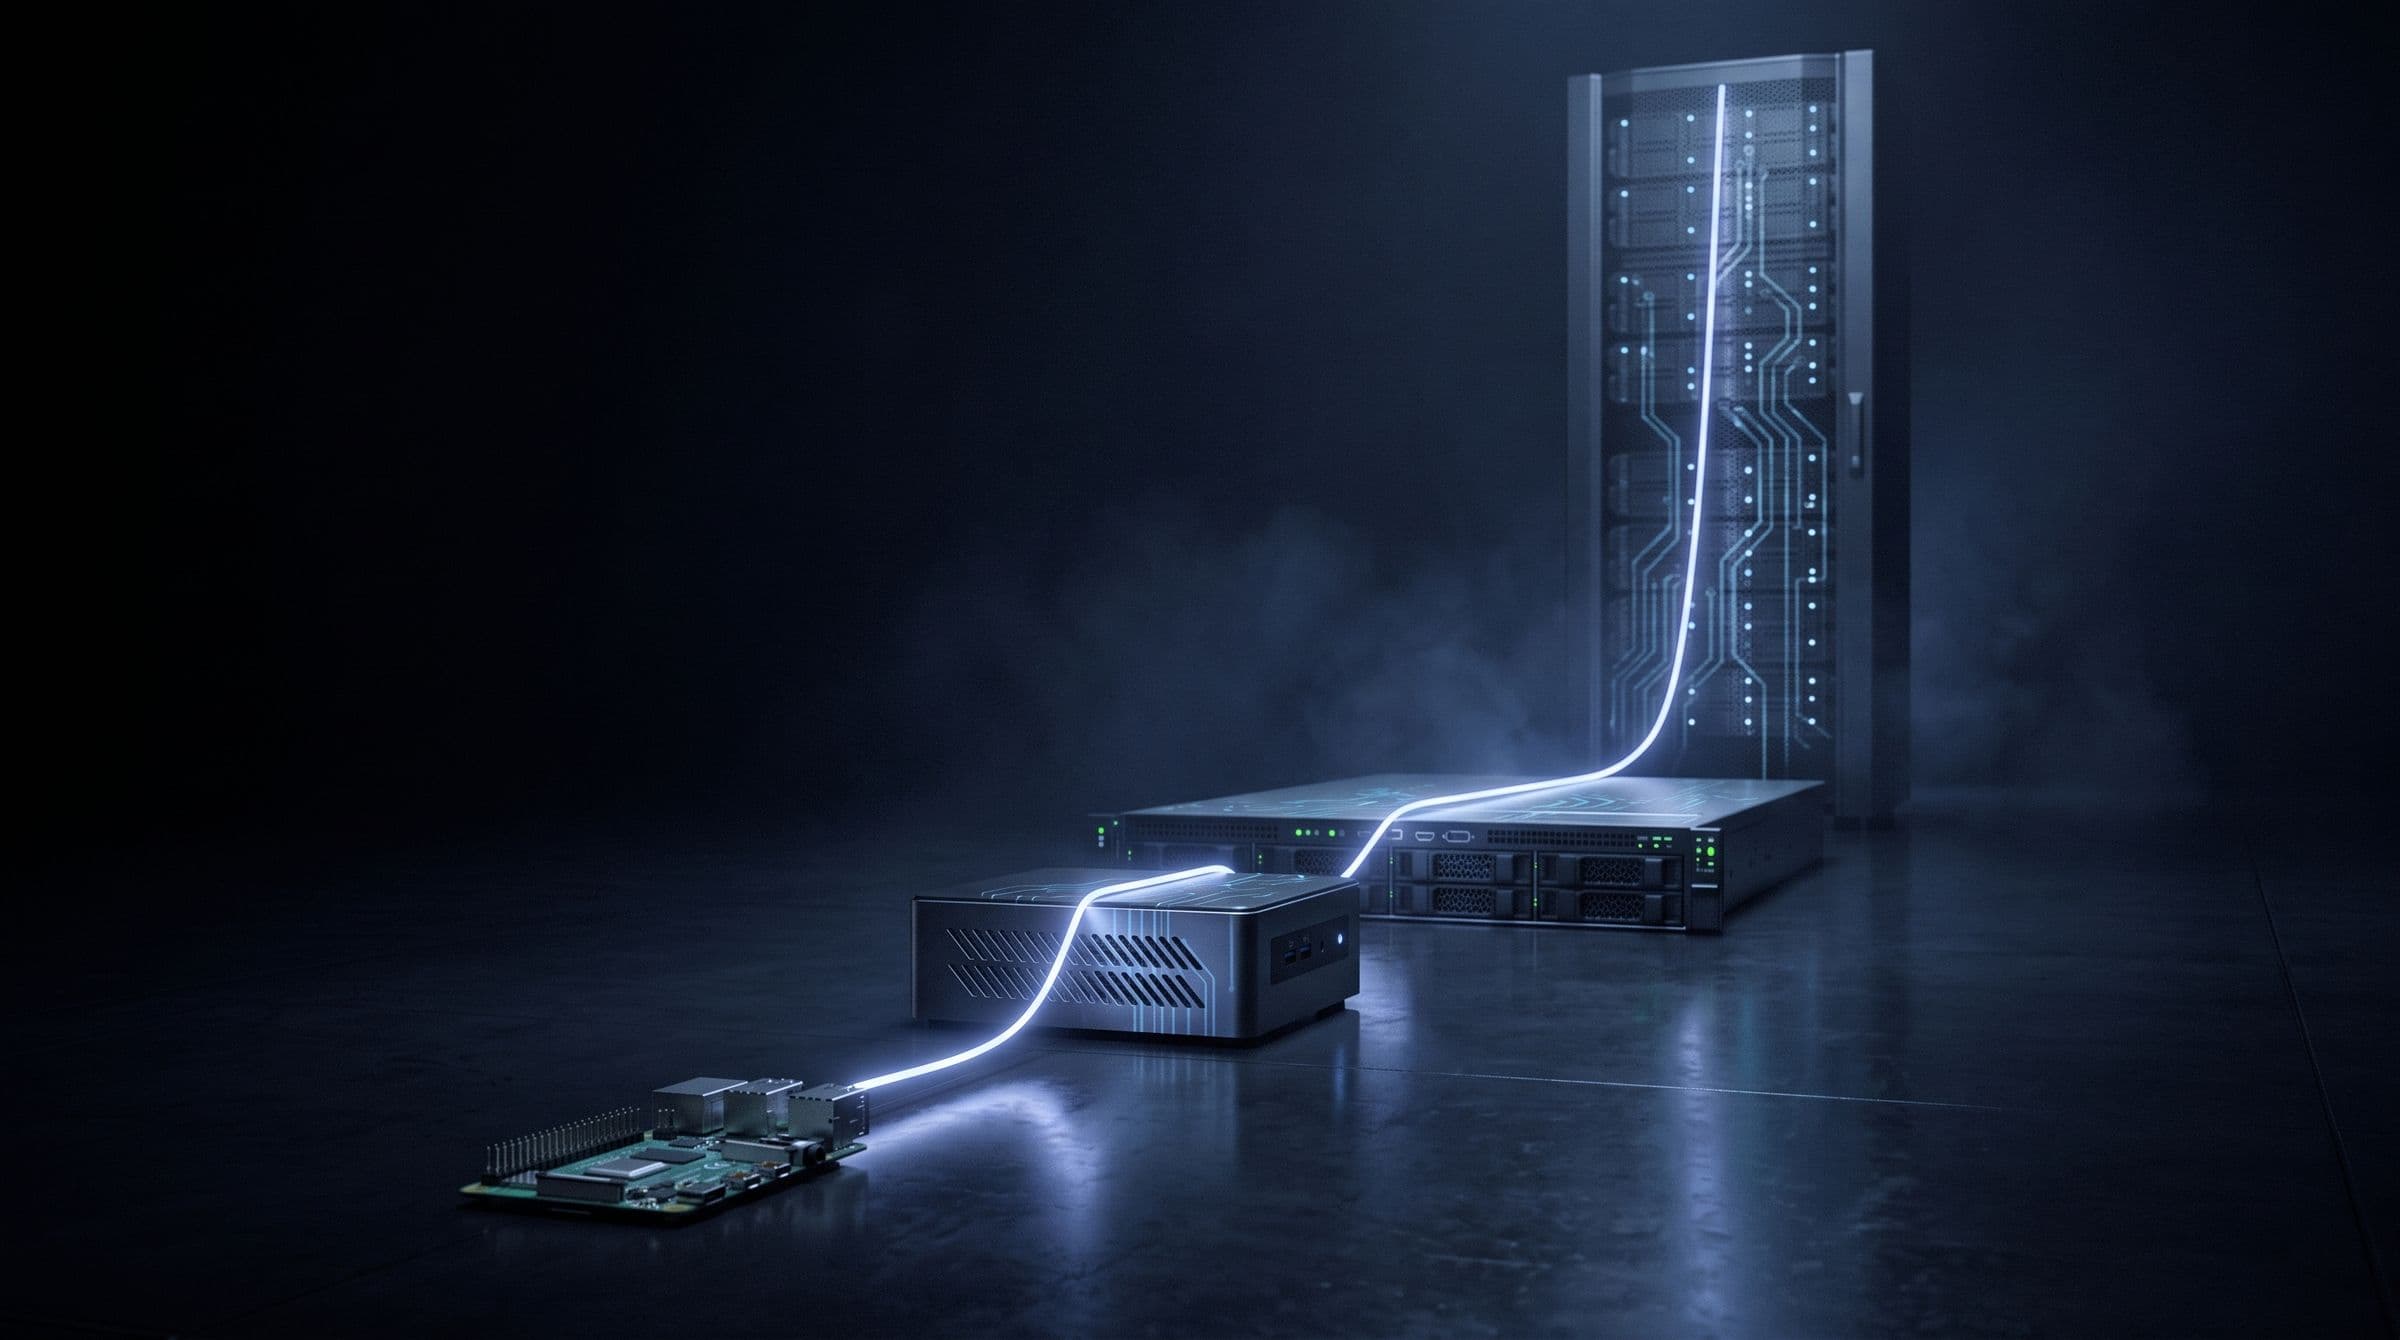 Edge AI
One Codebase From a Single-Board Computer to a Rack
Tenzro builds one node for every class of machine, from a Raspberry Pi to a GPU server, by varying compiled features and resource presets rather than forking the code. How the tiers work, what we measured, and why small devices belong in an AI network.
5 min read Model routing
Routing Across Many Providers, and Why Receipts Must Be Verifiable
A model router chooses on price, latency and standing, hedges the slow tail and fails over in seconds. None of that is trustworthy unless each answer comes with a receipt a third party can check. How Tenzro does both.
5 min read AI factories
Utilisation decides AI factory economics
An AI factory's accelerators cost the same whether they are busy or idle, so served work per installed accelerator is the number that matters. This article covers where utilisation is lost, and how matching demand across many operators recovers some of it.
5 min read Distributed computing
Multi-VM runtime: EVM and SVM on one ledger
How the Tenzro ledger runs the EVM and the SVM on one state, alongside native transactions, with one native TNZO balance and Block-STM parallel execution.
2 min read